
On this page
- Why batch size changes OCR output: GPU arithmetic and floating-point order
- Why reproducible OCR matters: audit, re-runs, regression tests, mixed batches
- How the OCR engine is made deterministic: fixed detector, line order and recognition batches
- Reproducibility test: 300 pages, bit-identical across batch sizes and processes
- OCR accuracy of the deterministic engine compared with the unmodified engine
- Reproducibility of the language-model path under load
- How to test OCR reproducibility on your own pages in an afternoon
- Sources
Run the same page alone, or in a batch of 8, or next to pages from other jobs. You should get the same words, the same boxes and the same confidence. The CTC engine behind the fast pipelines is built for exactly that and was measured on 300 pages.
Bit-identical output is the property of the CTC engine. In the language-model pipeline the text comes from a language model. Read one page at a time, that text is identical from run to run, also across restarts. With many pages in the model at once, a few pages differ in single words from the one-page reading (numbers in the last section).
Why batch size changes OCR output: GPU arithmetic and floating-point order
To keep a GPU busy, OCR systems process several pages or text lines in one call. That is called batching. It is fast, and it quietly changes the arithmetic. GPU code picks its method from the shape of the data, and floating-point sums depend on the order they are added in. So a line that is read alone and the same line read next to other lines can differ in the last digits of the confidence, and sometimes in a letter.
Batching pages for the text detector moved boxes by one pixel, and a batch of pages with different shapes did not run at all without padding. Every single run is correct in itself. The trouble starts when you compare two runs.
Why reproducible OCR matters: audit, re-runs, regression tests, mixed batches
- Audit. A reviewer asks why a field read 8 and not 3 last March. With identical output you can run the page again and get the same answer.
- Re-runs. A re-processed archive should differ from the first run only where you changed something on purpose.
- Tests. Regression tests on OCR output can compare bytes instead of tolerating noise.
- Mixed batches. Your page should not depend on which other customers' pages shared its batch.
How the OCR engine is made deterministic: fixed detector, line order and recognition batches
The reference engine fixes what varies:
- Detector: exactly one page per call. A page batch there moved boxes by a pixel.
- Reading order: lines are built from box centres, not from the corner coordinate.
- Recognition: every line crop is scaled to a fixed height, padded to the next of a fixed set of widths, and sent in fixed batches of 16. A short last batch is filled up with blank images. A line therefore always sees the same shape, whatever its neighbours are.
- Page batch: it decides only how many pages pool their crops into full batches; what any single line sees stays the same.
Reproducibility test: 300 pages, bit-identical across batch sizes and processes
300 public pages (18,786 text lines) ran through the engine in several set-ups, and the output files were compared byte for byte: text, boxes, confidence and count.
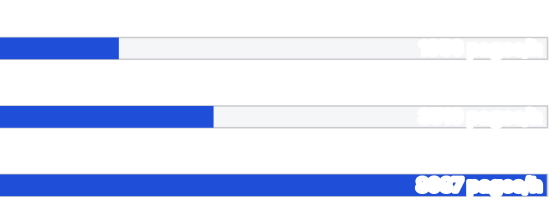
Throughput of three set-ups on the same 300 pages, development runs on one test GPU. The output of all three is bit-identical on all 300 pages.
| Set-up | Pages/h | GPU power | Same bytes as batch 1, of 300 pages |
|---|---|---|---|
| 1 process, page batch 1 | 1,953 | 71 W | reference |
| 3 processes, page batch 8 | 8,418 | 114 W | 300 |
| 3 processes, page batch 16 | 8,987 | 115 W | 300 |
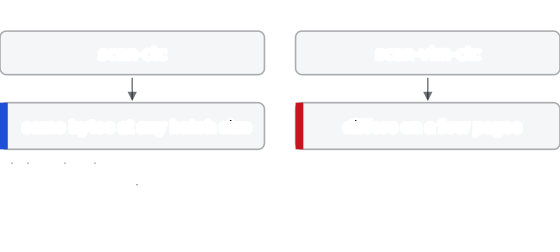
| 3 processes, recognition batch 8 | 7,437 | 119 W | 3 (297 differ) |
| 3 processes, recognition batch 4 | 9,839 | 123 W | 2 (298 differ) |
The first three rows: pooling pages from 1 to 16 and running three processes at once gives the same bytes on every page, and 4.6 times the pages per hour. The last two rows: changing the batch size inside the recognition step changes the output. So that value is fixed, and a different value would be a new pipeline version with its own name.
Arithmetic from the same table: 8,987 pages/h at 115 W is about 78 pages per watt-hour of GPU power, against about 27 for one process at 71 W. The GPU was busy 25 % of the time in the first set-up and about 60 % in the three-process ones.
These figures are from three processes on one test GPU, 4 Nov 2026.
A second test mixed pages from different jobs: 48 pages in 9 runs: 8 compositions and the single-page reference (batches of 8, 16 and 3, sorted by size, alternating large and small, reversed, with empty neighbours). 0 pages differed in any of the 9 runs.
OCR accuracy of the deterministic engine compared with the unmodified engine
Identical output says the result repeats; accuracy is a separate question. Compared with the unmodified engine, the reference engine returns the same line set on 197 of 300 pages, and 169 of 18,786 line texts differ. A random sample of 40 differing line pairs was judged against the page image, with the source of each reading hidden: 16 were better in the reference engine, 14 in the other, 5 equal, 5 undecidable. On a sample of this size the two engines are on par.
Reproducibility of the language-model path under load
The image-to-text language model path (where that model writes the text) varies with the load. In a run of the model alone at temperature 0, 6 to 11 % of the pages came out text-identical to the run with parallelism 1. In a measurement of the language-model pipeline on the test GPU, 20 of 20 pages were identical when run one after another, and 3 of 100 differed in their words at 32 pages at once and 16 of 200 (8 %) at 64 at once. By the counts of lines, words and characters alone, fewer pages differ: 2 of 100 and 9 of 200; the words are the stricter measure. The difference sits in the text of the model; the CTC part was the same in both runs. Bit-identical output is the property of the CTC OCR engine path.
How to test OCR reproducibility on your own pages in an afternoon
- Take 100 pages. Run each alone and save text, boxes and confidence.
- Run them again in a batch of 8, then mixed with other pages, then on a second process.
- Compare the files byte by byte. Count the pages that differ.
A count above zero is the amount of variation your downstream checks have to absorb.
Sources
| Statement | Where it comes from |
|---|---|
| 1,953, 3,510, 8,418, 8,987, 7,437, 9,839 pages/h; 71 to 123 W; bit-identical counts | measurement on 300 public pages, three processes, 2026-11-04 |
| 18,786 lines, 197 of 300 same line set, 169 differing lines, 40-pair sample | measurement, comparison against the unmodified engine, 2026-11-04 |
| 48 pages, 9 runs (8 compositions and the reference), 0 differing | mixed-batch test of 2026-11-04, development GPU |
| 78 and 27 pages per watt-hour, 4.6 times | arithmetic from the table (8,987 / 115; 1,953 / 71; 8,987 / 1,953) |
| 6 to 11 % text-identical for the language model | offline run of the language model on the hard test pages, temperature 0 |
| The language-model pipeline, one page at a time: 98 of 98 public pages identical across separate process starts (cache on and off); 20 of 20 identical one by one; 3 of 100 and 16 of 200 differ in their words at 32 and 64 at once | own measurement on the test GPU, 2026-11-06 |