
On this page
- OCR accents and diacritics: Ě read as Ė, É or ŘE on a Czech receipt
- OCR errors that look like words: Prosimé for Prosíme
- Missing price and cut product code: OCR output that looks complete
- Flagging OCR differences: how a second OCR engine marks these spots
- How the OCR readings are scored: printed text as reference
- Sources
Which OCR can you trust with an amount, an accent or a product code? A receipt is short, printed small, and full of numbers, names and accents. The same spot of a public receipt is shown here with what ten OCR engines wrote under it, next to two small crops of the printed spots. Most readings agree; the tables show where they differ.
The systems are labelled A to J; System A is the image-to-text model of the combined pipeline and System H is the CTC text reader. The comparison covers one receipt and one invoice.
OCR accents and diacritics: Ě read as Ė, É or ŘE on a Czech receipt
The headline of a Czech café receipt reads NA VŠE, CO DĚLÁME. The E has a caron.
| System (hardest-pages test) | What it wrote here | Compared with the print |
|---|---|---|
| Printed | NA VŠE, CO DĚLÁME, | |
| System A | NA VŠE, CO DĖLÁME, | differs: Ė for Ě |
| System B | NA VŠE, CO DŘELÁME, | differs: ŘE for Ě |
| System C | NA VŠE, CO DÉLÁME, | differs: É for Ě |
| System D | NA VỀE, CO DỰLÀME, | differs: Ề for Š; Ự for Ě; À for Á |
| System E | NA VŠE, CO DĚLÁME, | equals the print |
| System F | NA VŠE, CO DĚLÁME, | equals the print |
| System G | NA VŠE, CO DĚLÁME, | equals the print |
| System H | NA VŠE, CO DĚLÁME, | equals the print |
| System I | NA VŠE, CO DĚLÁME, | equals the print |
| System J | NA VŠE, CO DĚLÁME, | equals the print |
Six systems get it right. Four write another letter on the E: an E with a dot, an E with an acute, an R next to the E, and in one case a mess of letters with tone marks that exist in another script. Nothing in the output tells you which line is wrong. The line looks like text.
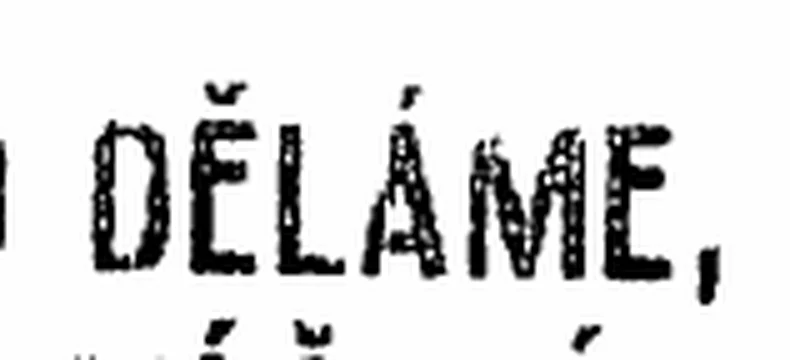
OCR errors that look like words: Prosimé for Prosíme
At the bottom of the same receipt is the request to keep the receipt. The print reads Prosíme pečlivě uschovejte.
| System (hardest-pages test) | What it wrote here | Compared with the print |
|---|---|---|
| Printed | Prosíme pečlivě uschovejte | |
| System A | Prosimé pečlivé uschovjte | differs: i for í; é for e; é for ě; missing: e |
| System B | Prosíme pečlivě uschovejte | equals the print |
| System C | Prosimé pečlivé uschovejte | differs: i for í; é for e; é for ě |
| System D | Prosíme pečlivě uschovejte | equals the print |
| System E | Prosíme pečlivě uschovejte | equals the print |
| System F | Prosíme pečlivě uschovejte | equals the print |
| System G | Prosíme pečlivě uschovějte | differs: ě for e |
| System H | Prosíme pečlivě uschovejte | equals the print |
| System I | Prosíme pečlivě uschovejte | equals the print |
| System J | Pros**í **íme pečlivě uschovejte | differs: extra: í |
Here a different group fails: two of the systems write Prosimé pečlivé, with an é where the print has an e or ě and an i without its accent. They are still words you could believe. A spell checker for Czech would catch it; a check that only looks at digits would not.
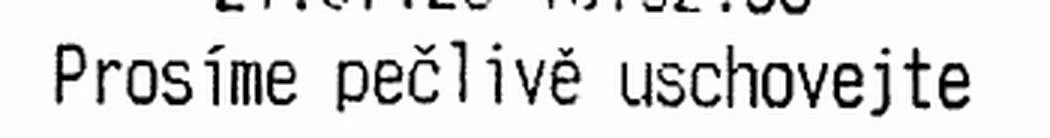
Missing price and cut product code: OCR output that looks complete
The first line of the items is a menu with the price 248.00 on the right.
| System (hardest-pages test) | What it wrote here | Compared with the print |
|---|---|---|
| Printed | 248.00 | |
| System A | 248.00 | equals the print |
| System B | 248.00 | equals the print |
| System C | 248.00 | equals the print |
| System D | - | not in the output |
| System E | 248.00 | equals the print |
| System F | - | not in the output |
| System G | 248.00 | equals the print |
| System H | 248.00 | equals the print |
| System I | 248.00 | equals the print |
| System J | 248.00 | equals the print |
Two systems leave the price out of their output altogether: the number is not there. For an invoice that is the worse case, because the line looks complete.
The same happens to a product code on the invoice, a line from a public invoice:
| System (hardest-pages test) | What it wrote here | Compared with the print |
|---|---|---|
| Printed | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | |
| System A | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System B | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System C | SanDisk U 64GB Kit | differs: missing: SDSQUAR-064G-GN6MA |
| System D | SanDisk U 64GB Kit | differs: missing: SDSQUAR-064G-GN6MA |
| System E | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System F | SanDisk U 64GB Kit | differs: missing: SDSQUAR-064G-GN6MA |
| System G | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System H | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System I | SanDisk U 64GB Kit SDSQUAR-064G-GN6MA | equals the print |
| System J | SanDisk u 64GB Kit SDSQUAR-064G-GN6MA | differs: u for U |
Three systems cut the line after the product name; the code SDSQUAR-064G-GN6MA is gone. The article number is the part a bookkeeper searches for.
Flagging OCR differences: how a second OCR engine marks these spots
The combined pipeline is built on the first system in the tables, a model that writes the page, plus a second OCR engine that finds every word on its own and reads it again. The model wrote DĖLÁME, in the headline. The second OCR engine read DĚLÁME,, and the word is flagged. At the request to keep the receipt, the model wrote Prosimé, and the OCR engine Prosím; flagged, together with the neighbouring words.
In the first case the OCR engine's reading is the one that matches the print. In the second case the OCR engine's reading cuts the word short. The second OCR engine makes its own mistakes, and the combination shows the split: the word is marked with its box, both readings and the OCR engine's confidence.
How the OCR readings are scored: printed text as reference
Prints and readings are compared by script, character by character, with the printed text as the reference for each spot. The two crops come from a public receipt.
Sources
| Statement | Where it comes from |
|---|---|
| Readings of the ten systems | hardest-pages test, output file of each system for the page; compared by script with the print |
| Flagged words and both readings | offline test of the combination, entries of the café receipt |