
On this page
- OCR model comparison table: target values found, wrong and missing
- OCR accents and diacritics: seven readings of a Czech headline
- OCR errors that look like words: seven readings of one sentence
- OCR model portraits: strengths, slips and speed of each model
- FireRed-OCR, version 7bf5e9d
- GLM-OCR, version 2e85a62
- LightOnOCR-2 1B bbox
- olmOCR 2 7B, version e52d6f09
- OvisOCR3, version 17f255e
- PaddleOCR-VL 1.6, version c5630ab
- PP-OCRv6
- Second OCR engine as a cross-check: flagged words on the café receipt
- Combined OCR pipeline: image-to-text model plus word-level CTC reader
- Basis of the comparison: run smoke-hart, ten hard pages
- Sources
Which OCR model reads your documents right? A model that is right in the headline can be wrong in the price, and the output looks equally tidy. Seven models ran on the same ten hard pages (named run smoke-hart). They are shown at the same spots, with the print beside each reading, and one short portrait per model further down.
Which means: you see what each model wrote where it counts, not a score. The four spots come from two public pages, a café receipt and an invoice; every reading is the model's own output, compared with the print by script.
OCR model comparison table: target values found, wrong and missing
The table is sorted by name, not by result. The target values are 135 values on six pages, checked by eye (run smoke-hart). The second table counts numbers on four pages that have a text layer to compare with. "Found in another form" means the same digits, but with other punctuation or an accent than the print, for example a decimal point where the page has a comma; the number is legible, the form is not the printed one.
| Model | Version | Found | Found in another form | Wrong | Missing |
|---|---|---|---|---|---|
| FireRed-OCR | 7bf5e9d | 107 | 4 | 2 | 22 |
| GLM-OCR | 2e85a62 | 110 | 3 | 4 | 18 |
| LightOnOCR-2 1B bbox | 101 | 10 | 8 | 16 | |
| olmOCR 2 7B | e52d6f09 | 103 | 3 | 8 | 21 |
| OvisOCR3 | 17f255e | 130 | 3 | 0 | 2 |
| PaddleOCR-VL 1.6 | c5630ab | 109 | 2 | 0 | 24 |
| PP-OCRv6 | 105 | 3 | 5 | 22 |
| Model, numbers on four text-layer pages (425 numbers) | Found | Found in another form | Wrong | Missing |
|---|---|---|---|---|
| FireRed-OCR | 202 | 189 | 16 | 18 |
| GLM-OCR | 259 | 152 | 0 | 14 |
| LightOnOCR-2 1B bbox | 304 | 45 | 13 | 63 |
| olmOCR 2 7B | 323 | 50 | 17 | 35 |
| PaddleOCR-VL 1.6 | 283 | 59 | 2 | 81 |
| PP-OCRv6 | 330 | 87 | 5 | 3 |
A wrong value is a different value in the output, with no mark that says so. A missing value is not in the output at all. For an invoice both matter: the first is the number you book wrongly, the second is the line you never see.
OCR accents and diacritics: seven readings of a Czech headline
The headline of the café receipt reads NA VŠE, CO DĚLÁME in print. The Ě carries a caron.
| Model (run smoke-hart) | What it wrote | Compared with the print |
|---|---|---|
| Printed | NA VŠE, CO DĚLÁME, | |
| FireRed-OCR | NA VŠE, CO DÉLÁME, | differs: É for Ě |
| GLM-OCR | NA VŠE, CO DŘELÁME, | differs: ŘE for Ě |
| LightOnOCR-2 1B bbox | NA VŠE, CO DĚLÁME, | equals the print |
| olmOCR 2 7B | NA VŠE, CO DĚLÁME, | equals the print |
| OvisOCR3 | NA VŠE, CO DĖLÁME, | differs: Ė for Ě |
| PaddleOCR-VL 1.6 | NA VỀE, CO DỰLÀME, | differs: three letters |
| PP-OCRv6 | NA VŠE, CO DĚLÁME, | equals the print |
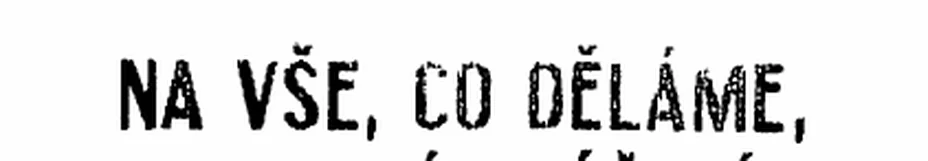
Four of the seven change a letter here, and nothing in the output marks which line to check. The line looks like Czech. The one that went furthest wrote tone marks from another script.
OCR errors that look like words: seven readings of one sentence
Further down the same receipt stands the request to keep it: Prosíme pečlivě uschovejte.
| Model (run smoke-hart) | What it wrote | Compared with the print |
|---|---|---|
| Printed | Prosíme pečlivě uschovejte | |
| FireRed-OCR | Prosimé pečlivé uschovejte | differs: three letters |
| GLM-OCR | Prosíme pečlivě uschovejte | equals the print |
| LightOnOCR-2 1B bbox | Prosime pečlivé uschovejte | differs: two letters |
| olmOCR 2 7B | Prosíme pečlivě uschovějte | differs: ě for e |
| OvisOCR3 | Prosimé pečlivé uschovjte | differs: three letters, one missing |
| PaddleOCR-VL 1.6 | Prosíme pečlivě uschovejte | equals the print |
| PP-OCRv6 | Prosíme pečlivě uschovejte | equals the print |
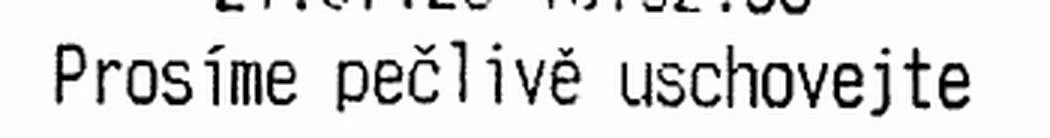
Whoever slipped at the headline is not the one who slipped here. Each model gets its own paragraph below.
OCR model portraits: strengths, slips and speed of each model
This is a comparison of two outputs from the same run, not a run of this model inside the combined pipeline.
FireRed-OCR, version 7bf5e9d
It held on the prices: 248.00 came out on a line of its own, as printed, and it returns a probability per token. It slipped on the accents of both Czech spots, and the product line of the invoice is not in its output. In the plain run two pages stopped in a repetition loop; in the serving test 1, 2 and 6 answers did not end with a normal stop at 1, 8 and 32 requests at once (run smoke-hart-vllm), which ran at 286 pages an hour with one request and 1,028 with 32. Of the 434 single parts that make up the target values it found 241, and it returns no boxes. The second OCR engine read headline and request as printed, so both would be flagged; the price agrees. OvisOCR3 wrote the same Prosimé pečlivé on the request, so the two slipped on the same letters.
GLM-OCR, version 2e85a62
It held on the request and on the first menu line, where the price 248.00 sits on the same line as the item, as on the paper. It slipped in the headline (DŘELÁME, a word that looks like a word) and on the invoice, where the product line came without its unit price: the line looks complete, the number is not there. It needed 5,522 MiB of GPU memory at its peak, and a serving engine ran it at 1,955 pages an hour with 32 requests at once (run smoke-hart-vllm). None of its four wrong target values was marked in the output, since it returns text and a probability per token but no boxes. The second OCR engine read DĚLÁME as printed, so the headline would be flagged; a price the model left out would show up as a word only the OCR engine found.
LightOnOCR-2 1B bbox
It held on three spots: the headline, the first menu line and the product line with its article number all match the print, the last as a table cell with line breaks. It also returns a box per block and a probability per token. It slipped in the request, where the í lost its accent and the ě became an é, and on the four text-layer pages 63 of 425 numbers are missing. It needed 7.99 seconds per page in the plain run and 11,944 MiB of GPU memory; one page was cut off before the end. The second OCR engine read Prosíme with its accent, so the request would be flagged; at the other three spots the two agree.
olmOCR 2 7B, version e52d6f09
It held on the headline, and on the invoice it wrote the product line with the article number as a table cell, the way it writes tables: as HTML. On the text pages one page scored a character error rate of 0.016, and it found 323 of 425 numbers. It slipped by adding marks that are absent from the print: Bruselská for the printed Bruselska on the menu line, and an ě in uschovejte. It returns no boxes and no confidence, needed 16,946 MiB of GPU memory at its peak, and two pages were cut off before the end. The second OCR engine read both words as printed, so both spots would be flagged; at the headline and the product line the two agree.
OvisOCR3, version 17f255e
This is the writing model of the combined pipeline. At the first menu line it wrote the price 248.00, and on the invoice the product line with the article number, which three other systems cut off in the earlier one spot, ten systems test. It slips on accents: a dotted Ė for the Ě of the headline, and Prosimé pečlivé uschovjte in the request. Its target values are the most complete of the seven here, with none wrong. The words the second engine flagged on the café receipt are listed in the next section; how the model sits in the pipelines is in OCR pipeline models.
PaddleOCR-VL 1.6, version c5630ab
Running text is its strength: the request came out letter for letter. It slipped in the headline, where three words carry tone marks from Vietnamese, and on the dense part of the café receipt it left out the prices of all three items and the order numbers; the product line of the invoice is missing as well. No target value was wrong, they were missing, and the output gives no confidence, so a left-out column is not marked. A serving engine ran it at 812 pages an hour with one request, 2,953 with 8 and 3,907 with 32 at once (run smoke-hart-vllm); it took 14,266 MiB of GPU memory in the plain run. The second OCR engine would flag the headline; the price 248.00 and the product code are on its word list, so they would be there as words only it found.
PP-OCRv6
This is the second OCR engine itself, and no writing model: it cuts the page into lines and reads each line character by character. At all four spots its reading equals the print, accents included; the invoice line came as two lines. It is fast and small, 1.06 seconds per page and 2,986 MiB of GPU memory at its peak, and each line carries a box and a confidence. Its limit is the page as a whole: on the four text-layer pages the character error rate was 0.461 when the reading order counts and 0.058 when only the set of words counts. The words are there; the order is not. Its predecessor PP-OCRv5 found 90 target values with 8 wrong in the same run, at 0.71 seconds per page.
Second OCR engine as a cross-check: flagged words on the café receipt
The combination checks the writing model word by word. The second OCR engine, PP-OCRv6, finds the box of every word and reads it again; where the readings differ, the word is flagged. Seven words of the café receipt were flagged (two are number strings). Five of them, with both readings:
| OvisOCR3 wrote | PP-OCRv6 read | Confidence | Flag |
|---|---|---|---|
| DĖLÁME, | DĚLÁME, | 0.924 | differs |
| VÁS | VÁ | 0.988 | differs |
| pečlivé | pečliv | 0.997 | differs |
| uschovjte | uschovejt | 0.997 | differs |
| Prosimé | Prosím | 0.997 | differs |
At the headline the second engine read the Ě that the print has. Where it is not right either, the flag still says that the two disagree.
Combined OCR pipeline: image-to-text model plus word-level CTC reader
In the combined pipeline a writing model writes the page, and a second OCR engine finds every word again, gives it a box and flags the words where the two readings differ. The model writes the page, the engine finds every word on it again, and the spots above show why the two belong together: where the writing model changed a letter, the line reader had it right, and where the line reader loses the order, the writing model keeps it. A flag says that the two readings differ; it does not say which one is right.
Basis of the comparison: run smoke-hart, ten hard pages
Every figure on this page comes from run smoke-hart: ten hard pages, each model run once, one page at a time. The 135 target values sit on six of the pages and were checked by eye; the number lists on the other four pages are scored against their text layer.
Sources
Flagged words and both readings: offline test of the combination, entries of the café receipt. Readings of all seven models at the two spots are the output of run smoke-hart for the public café receipt and invoice, compared with the print by script. The counts come from the scoring file of the run, speeds at one, eight and 32 requests from run smoke-hart-vllm, time and memory from the timing and memory logs of each model.