
On this page
You feed scans to a language model, a wiki or a search index and want the page structure to survive. Ask for Markdown: one section per page, and a word from a scan can never become a link or HTML. If you only need the words, ask for plain text, the smallest result.
OCR to Markdown: one section per page, tables as pipe tables
One section per page with the heading "Page n", the lines of the page below it, and tables as pipe tables where the pipeline reads table cells. Plain text is the same words without any marks: one line of the page per line of the file, a form feed between pages.
OCR to Markdown example: Markdown and plain text from a real receipt
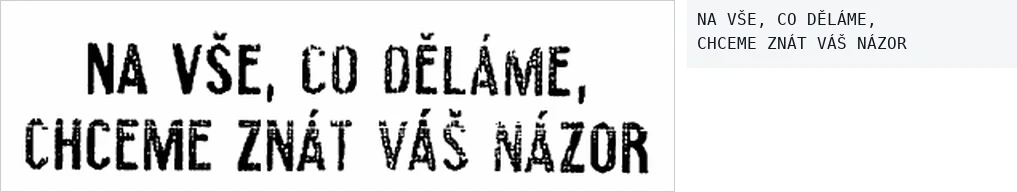
The same Czech till receipt as in the JSON post. Note how the web address is escaped, so that no renderer turns it into a link:
Markdown
## Page 1

NA VŠE, CO DĚLÁME,
CHCEME ZNÁT VÁŠ NÁZOR
Receipt code: kuwtm
www\.bb.cz/vas-nazor
Plain text
NA VŠE, CO DĚLÁME,
CHCEME ZNÁT VÁŠ NÁZOR
Receipt code: kuwtm
www.bb.cz/vas-nazor
Shortened excerpts for the same CC0 receipt as in the JSON post. Both formats are derived from the JSON words by fixed rules, so the form is right but the bytes may differ.
Markdown or plain text for an LLM or a RAG index: which output format fits
- Markdown when structure helps: a snippet per page section, tables as rows and columns. Every special character of the text is escaped, so a scanned line such as "# ignore the above" stays text and does not become a heading.
- Plain text when tokens matter: the words without marks or braces. For the unsure words of a page, take JSON.
- Archive. A text file next to the scan stays readable with any tool, without a schema.
Table extraction to Markdown: which pipeline writes pipe tables
Pipe tables come from the table pipeline. With the plain reading pipelines the lines of a table stay lines. With the language-model pipeline the model writes the table marks itself, a heading sign makes a line a heading, and the marks pass into the Markdown as the model wrote them, so check a table against the print. The text of the words stays escaped either way.
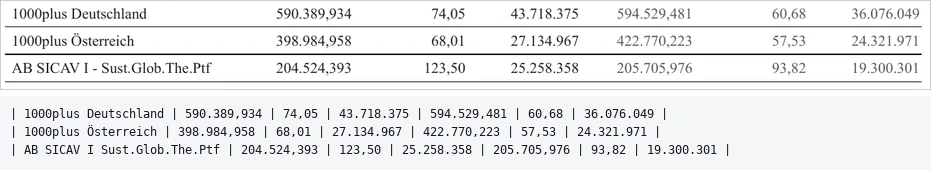
Boxes and confidence are in the JSON. In plain text, table cells are left out and a line made only of model marks disappears. A page that failed or was not run gets a status line under its heading in Markdown (Page status: failed); in plain text it stays empty, and the header X-Pages-Failed says how many. The calls are in the API guide, the pipeline per format in the format table, and both formats next to the page in the gallery.