Extract tables from PDFs and scans, cell by cell
You copy a table out of a PDF and paste it into Excel. Every row lands in one cell, and the numbers have lost their columns. Which means: a table that comes back as cells, each with a box and a confidence, keeps its columns and shows you the shaky cells to check.
Pick one page with a table and read it free: every word comes back with its box, the pieces a grid is built from.
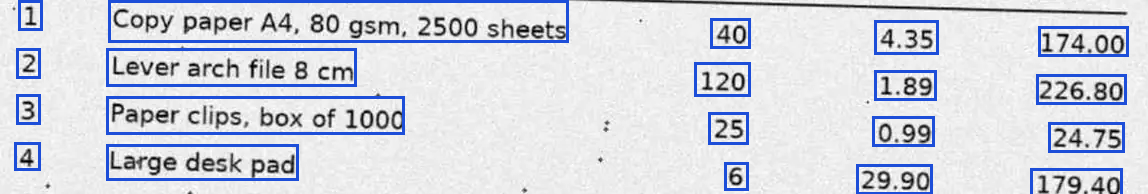
Table Every cell of the first four rows with its own box, each 0.99 sure or more. Boxes: as returned by a pipeline.

PDF table to Excel: cells instead of pasted text
Copying text gives you the words in some order. A table needs more:
Cell
Which word sits in which cell.
Span
Which cells span several rows or columns.
Header
Which row is the header.
So the OCR engine has to return the position of every word.
How well OCR reads tables: 35 tables measured
The table engine was scored on 35 tables with a known grid, 12 of them from scans.
| Result | What it is |
|---|---|
| 22 of 35 | tables found by the page layout step: 18 of 23 digital tables, 4 of 12 on scans. |
| 0.763 TEDS | grid quality of the table engine when it is given the table: 0.838 on digital tables, 0.617 on scans. |
TEDS is a score from 0 to 1 for how closely a returned table matches the true one, in grid and cell text; 1 is an exact match. The result holds cells with their boxes.
Source: run on 35 tables with the table engine. Read more: the table engine and which tools keep the grid
Table OCR on scans: what to check
- Scans: the detector finds the table only sometimes (4 of 12), and the grid starts where the table is found.
- Digits in the wrong cell: a check of the cells against their totals finds them.
- Two-level headers and merged cells.
How to extract a table from a PDF in five steps
- Send the page with
format=json: every word returns with a box and a confidence. - Take the words whose box lies inside the table.
- Cluster the boxes into rows by vertical center and into columns by left and right edge.
- Put each word into the cell where its box overlaps most.
- Check totals against their parts; list low-confidence words for a person.
The table pipeline returns tables too. On a scan where the layout step finds no table, steps 2 to 4 build the grid from the word boxes alone. Write the grid into your sheet from the JSON; the Markdown format carries tables from the table pipeline. Spans come back, and the totals check in step 5 shows where a number landed in the wrong cell.
Try table extraction free on your own page
Read one page of your own free to see the word boxes, or open the OCR demo gallery to see tables read as cells with their boxes.
Production use, high volume or your own server?
Private use and tests are free. For a company in production, a server of your own or a pipeline built on your pages, send the kind of page and the volume, and get a written offer, or a clear no when the fit is not there.
