Custom OCR pipeline for your invoices, forms or registers
No single OCR is best on every document. What if the OCR steps were built around your invoices, forms or old registers, and measured on them?
Price: on request.
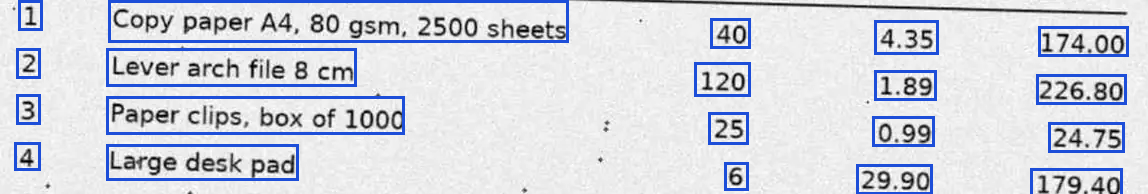
Table Every cell of the first four rows with its own box, each 0.99 sure or more. Boxes: as returned by a pipeline.

Custom OCR pipeline for your hard pages
A general pipeline
Built for a wide range of pages.
Your stack
One form, one stamp style or one old typeface: a narrower case. It can be tuned, and the gain is shown on your sample.
From your sample to a pinned OCR pipeline
Send a sample
Pages that your last tool got wrong, and the values you need from them.
See the gap
The standard pipelines read them, and what is missing or silently wrong is counted.
Get a pinned pipeline
A named version for your document type, with the numbers measured on your sample.
What a custom OCR pipeline delivers
- A pipeline for your document type.
- A name and a version,
name@version, so a result can always be traced to the steps that made it, and a version stays fixed. - Numbers measured on a sample of your pages, with their source, and the count before you sign.
- The same word-level result as every other pipeline: text, box and confidence.
Timing and price depend on your documents and go into a written offer. A mixed stack reads with one of the standard pipelines. A custom pipeline runs on your own on-premise server, so the pages stay in the building.
Production use, high volume or your own server?
Private use and tests are free. For a company in production, a server of your own or a pipeline built on your pages, send the kind of page and the volume, and get a written offer, or a clear no when the fit is not there.
