
On this page
Your archive tool or viewer already speaks hOCR and needs the text with its place on the page. Ask for hOCR: an open format that puts both into one HTML file. It fits when a tool of yours reads hOCR; for programs that consume the words directly, JSON is the compact choice.
What is hOCR? OCR output as XHTML with word bounding boxes and confidence
XHTML in which every page, line and word is an element whose title carries its box (bbox) and, for words, a confidence (x_wconf). The box is in pixels of the page image.
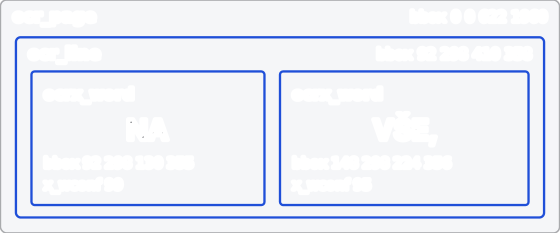
hOCR example: ocrx_word with bbox and x_wconf from an OCR API
The first words of the Czech till receipt as hOCR, on word level:
<div class='ocr_page' id='page_1' title='bbox 0 0 622 1960; ppageno 0'>
<span class='ocr_line' id='line_1_1' title='bbox 95 298 263 356'><span class='ocrx_word'
  id='word_1_1_1' title='bbox 95 298 132 354; x_wconf 92'>NA</span> <span class='ocrx_word'
  id='word_1_1_2' title='bbox 148 299 211 356; x_wconf 92'>VŠE,</span> <span class='ocrx_word'
  id='word_1_1_3' title='bbox 229 299 263 356; x_wconf 92'>CO</span> ...</span>
...
</div>
Shortened excerpt for the same CC0 receipt as in the JSON post. hOCR is derived from the JSON words by fixed rules, so the form is right but the bytes may differ.
What hOCR is used for: searchable PDF, text highlighting, cutting fields from a scan
Many archive and conversion tools take hOCR to build a searchable PDF or to show the text on the page image. A viewer uses the word boxes to highlight a hit, and you can cut a field out of the scan by its box. Use hOCR when the receiving tool asks for it by name.
hOCR levels per pipeline: word level, line level and failed pages
Word level (ocrx_word with its own box) comes with the pipelines that read words; the others deliver line level: one box per line, the text of the line as one element. hOCR carries pages, lines and words; tables and layout blocks are in the JSON. A page that failed or was not run appears as an empty page with a status entry, which marks it as unread rather than read and empty. Which pipeline gives which level is in the format table; the boxes next to the page are in the gallery.