PDF to Markdown for RAG: scans read by OCR, one section per page
You feed PDFs to a language model or a search index, and the scans come out empty or the tables as a heap of numbers. Ask for Markdown: scans are read by OCR, every page is one section, and tables from the table pipeline are pipe tables. Which means: your index holds text per page that you can cite by page number.
Send one page of your PDF, scanned or digital, and see the words come back, free.
PDF to Markdown API: what the Markdown looks like
One section per page with the heading ## Page n, the lines of the page below it. A word from a scan can never become a link or HTML: every special character is escaped, so a scanned line such as # ignore the above stays text and does not become a heading. For a Czech till receipt:
## Page 1

NA VŠE, CO DĚLÁME,
CHCEME ZNÁT VÁŠ NÁZOR
Receipt code: kuwtm
www\.bb.cz/vas-nazor
An excerpt of the CC0 receipt from the JSON post. The web address is escaped so that no renderer turns it into a link.
How to get Markdown from a scanned PDF with curl
Send the document, wait for the job, fetch the result as md:
curl -s -X POST "https://api.ocr-software.com/v1/jobs?pipeline=scan-ctc@2&formats=md" \
  -H "Authorization: Bearer $OCR_KEY" --data-binary @report.pdf    # answer: {"job_id": "..."}
curl -s "https://api.ocr-software.com/v1/jobs/$JOB_ID/result?format=md" \
  -H "Authorization: Bearer $OCR_KEY" -o report.md
Read more: the API guide
Markdown, text or JSON for a RAG index: which output format fits
| You want | Format |
|---|---|
| Structure per page and tables as rows and columns | md |
| The fewest tokens: only the words | text |
| The unsure words, boxes to point at the page | json |
Markdown fits a snippet per page section. Plain text is the same words without marks, one line of the page per line. The format reference lists the pipelines for each.
PDF tables to Markdown: which pipeline writes pipe tables
Only the table pipeline writes pipe tables. With the plain reading pipelines, the lines of a table stay lines. With the language-model pipeline, the model writes the table marks itself and they pass into the Markdown as written, so check a table against the print.
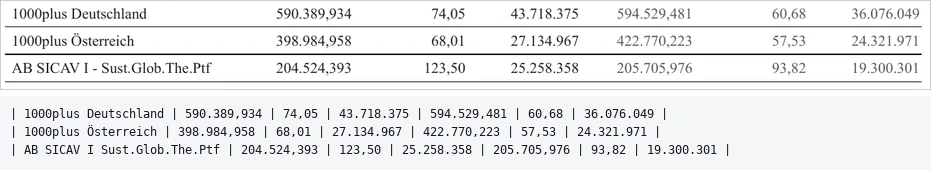
Table A table in Markdown, as the language model wrote it. Check a table like this against the print.
The page layout step found 22 of 35 tables in our test, 4 of 12 on scans. How the grid is measured: extract tables.
Pages that failed are marked, never empty
A page that failed or was not run gets a status line under its heading (Page status: failed), and the header X-Pages-Failed says how many. Your index never mistakes an unread page for a blank one. A document of up to 100 MiB and 1,000 pages goes through the API.
For an archive that people search in a PDF viewer, take the searchable PDF instead.
Try PDF to Markdown free on your own page
Read one page of your own free to see the words and their boxes, or open the OCR demo gallery to see tables and text read side by side.
Production use, high volume or your own server?
Private use and tests are free. For a company in production, a server of your own or a pipeline built on your pages, send the kind of page and the volume, and get a written offer.
