Make a scanned PDF searchable: your original plus an invisible text layer
The scans in your archive stay closed to search. Send them and get back the same PDF: it looks exactly like the scan, and every word can be found, selected and copied. Which means: a clerk searches a whole archive with Ctrl+F and copies an amount out of a scan instead of typing it.
Pick one page of your scan and read it free: you see the words, each at its box, that the text layer is made of.
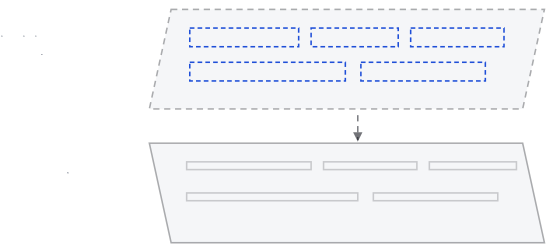
Layers The picture is not touched. The text sits invisibly on top, where each word or line sits on the page.
What a searchable PDF gives you
Same look
The scan stays as it was, pixel for pixel. Nobody has to relearn a document.
Full-text search
Any PDF viewer finds a word, a name or a number across the file.
Copy and select
A clerk marks an amount in the scan and pastes it into the booking.
How to make a scanned PDF searchable with two curl calls
Read the document, then fetch the PDF. Documents are deleted when the job ends, so the second call sends your original again:
curl -s -X POST "https://api.ocr-software.com/v1/jobs?pipeline=scan-ctc@2&formats=pdf" \
  -H "Authorization: Bearer $OCR_KEY" --data-binary @scan.pdf    # answer: {"job_id": "..."}
curl -X POST "https://api.ocr-software.com/v1/jobs/$JOB_ID/result?format=pdf" \
  -H "Authorization: Bearer $OCR_KEY" -H "Content-Type: application/pdf" \
  --data-binary @scan.pdf -o scan.searchable.pdf
A plain GET answers 422 source_required. An original whose page count or page size differs from the job answers 422 source_mismatch, so the text layer always sits on the right pages. Wait for the job to finish first: the API guide shows how.
Read more: the searchable PDF format
Check the OCR text layer with pdftotext
Any PDF tool shows what the layer holds. For a Czech till receipt, the first two lines:
pdftotext -layout scan.searchable.pdf - | head -n 2
NA VŠE, CO DĚLÁME,
CHCEME ZNÁT VÁŠ NÁZOR
The first lines of the CC0 receipt from the JSON post.
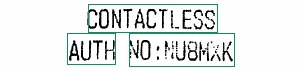
Layer The text layer sits at the words.
Word level or line level: which pipeline sets the text layer
| Pipeline | Text layer |
|---|---|
| A pipeline that reads word boxes | one piece of text per word, each at its box |
| The other pipelines | one piece of text per line, stretched over the line |
Search and page selection work with both. With a line layer, a single selected word can sit a few points off.
Searchable PDF for an archive: an unread page is never blank
A page that could not be read gets a visible strip at the top, OCR FAILED or OCR NOT RUN, and the response header X-Pages-Unread names it. So an archive never holds a page that looks searched and is not. A document of up to 100 MiB and 1,000 pages goes through the API as PDF, PNG, JPEG or multi-page TIFF. Contracts and statements stay in your own network when this runs on your own server.
For a language model, PDF to Markdown is the better output: the same words, one section per page.
Try a searchable PDF free on your own page
Read one page of your own free to see the word boxes, or open the OCR demo gallery to see a page read word by word.
Production use, high volume or your own server?
Private use and tests are free. For a company in production, a server of your own or a pipeline built on your pages, send the kind of page and the volume, and get a written offer.
